Code review separated the field.
Most runs found the two planted defects in the limiter. DeepSeek’s thick review missed the bigger one: prune compares an object to a number, so it never runs. It caught the reset bug, but not the type mismatch.
A creative benchmark in eight prompts
A poster, an interface, a critique, a title sequence, an explainer, a story, a parser and a code review. Here is what came back.
Three things matter more than a ranking.
Most runs found the two planted defects in the limiter. DeepSeek’s thick review missed the bigger one: prune compares an object to a number, so it never runs. It caught the reset bug, but not the type mismatch.
Muse Spark’s saved files were rewritten, not copied: four artifacts in run 1 and seven in run 2. Treat those runs as process demos, not as the model’s one-shot output.
See a trimmed artifact beside a clean oneHY4 Flash and Claude Haiku 5.5 (run 2) used no subagent tools and saved every file exactly. DeepSeek’s subagents made 363 tool calls, browser screenshots included. GPT’s loaded 29 skills.
Browse the clean runEight runs across six model families. The small line under each name is the run caveat.
Subagents used a browser to refine their work.
One malformed CSS line was repaired after saving.
Subagents loaded skills; two files were edited after saving.
One review arrived without a fenced block.
No subagent tools; one identical retry.
No subagent tools; all 16 files byte-exact.
Four visual files were saved trimmed.
Seven files saved trimmed; three prompts re-run after wording errors.
Three clean artifacts, chosen because they show the range of the prompts.
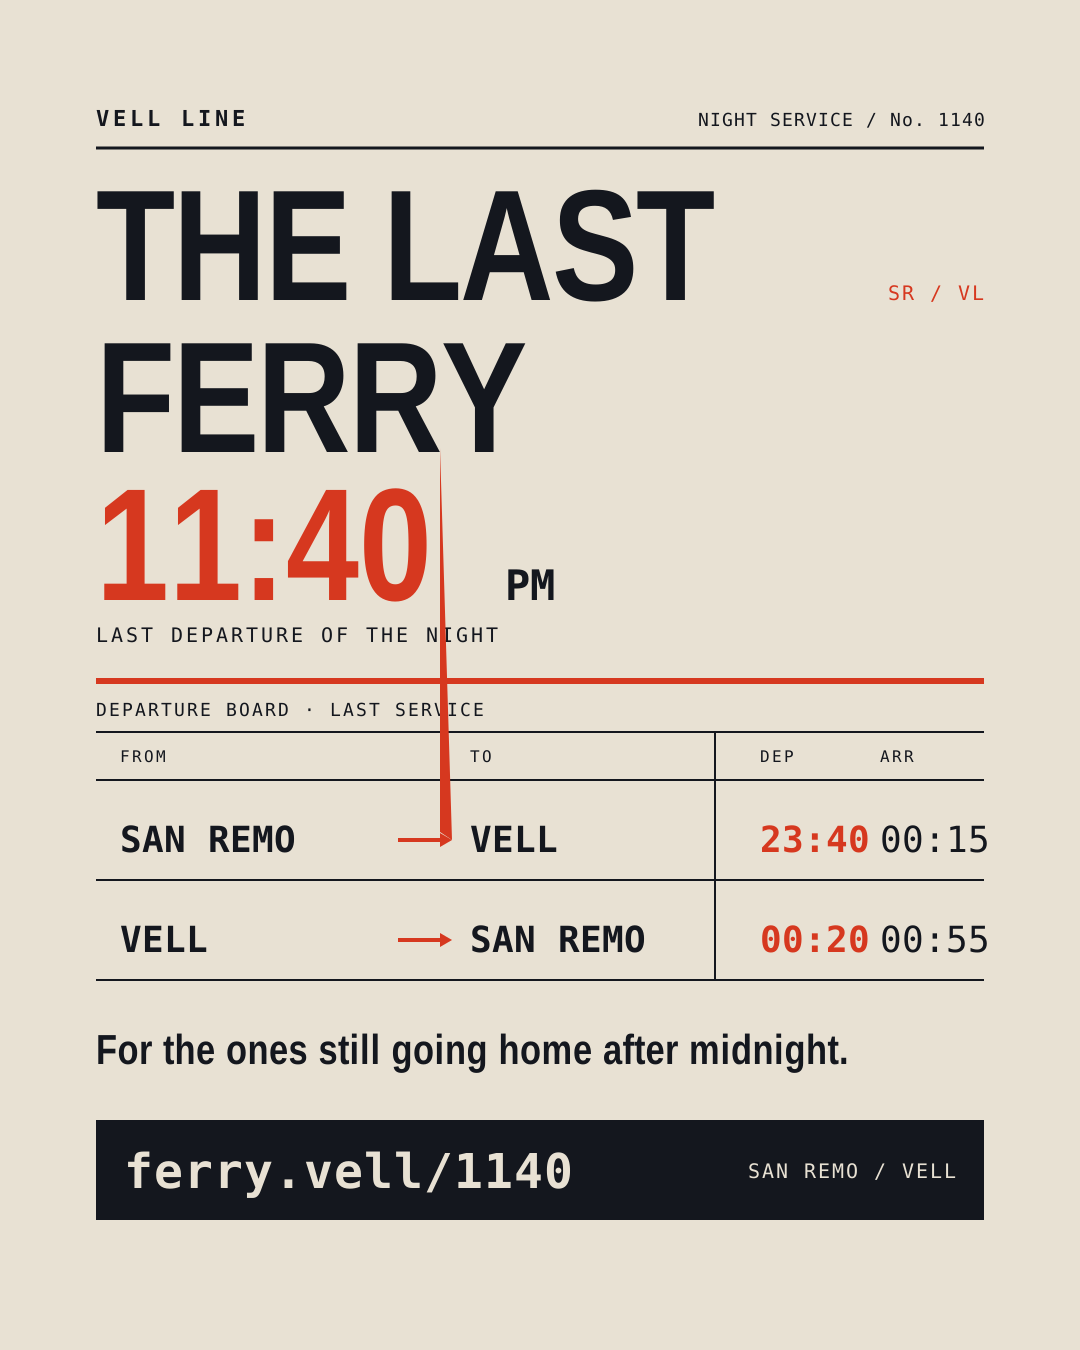
A poster with two inks and a hard timetable geometry.
A handwriting-to-LaTeX hero that shows the product instead of describing it.
An eight-second loop with a restrained title treatment.
Every task has a thin brief and a thick brief. Open a task to see all sixteen results.
How to read this
There is no invented score for a poster, an interface or a story. The parser and code-review tasks carry a short editorial note about what worked, what broke, or what missed the brief.
Read the method and caveats